
The short answer: GPUs are not disappearing, but they are no longer the default
The ability to run a 34.7-billion-parameter AI model on a laptop does not eliminate the need for advanced GPUs. It does challenge an expensive assumption: that every meaningful enterprise AI application requires the cloud, a powerful accelerator, or a major infrastructure investment from day one.
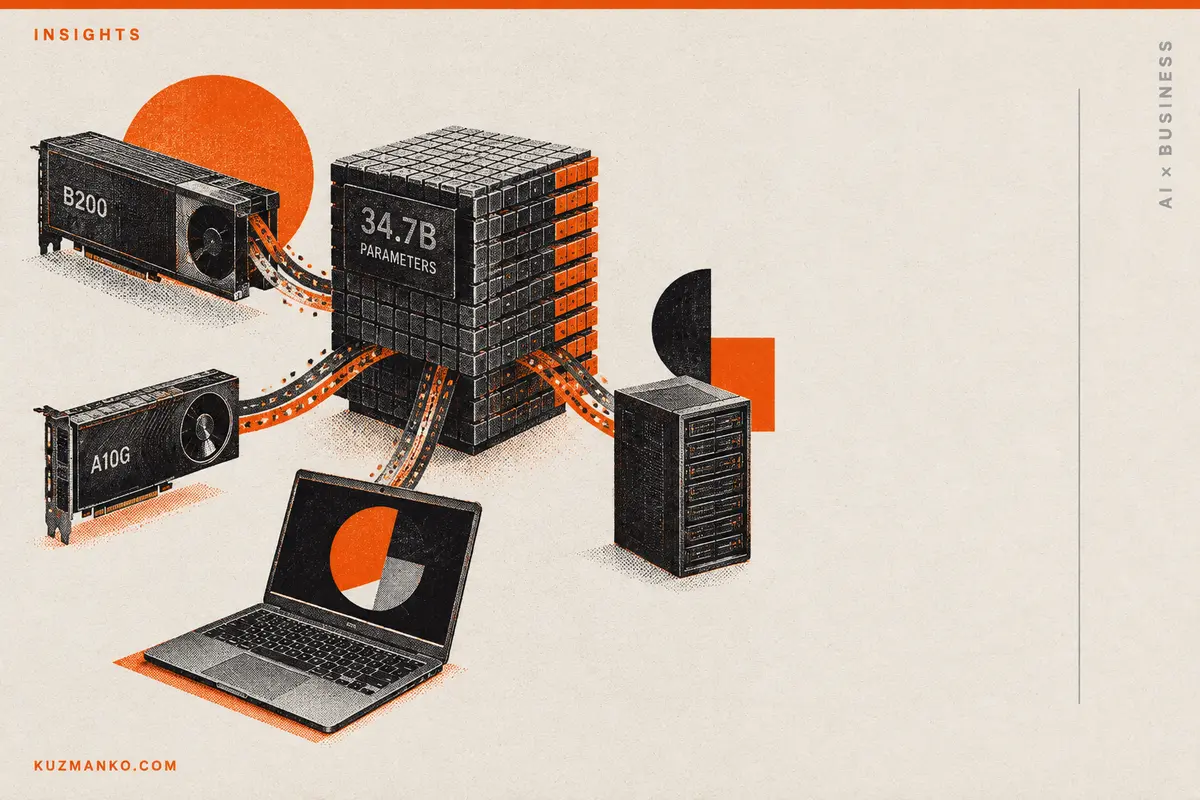
The important development around Ourbox-35B-JGOS and the VKUE inference engine is not simply that the model runs. It is how Mixture of Experts architecture, quantization, and memory management allow each token to use only about 3 billion active parameters. The result is a model with substantial overall capacity and structure, but a lower inference burden.
- 34.7 billion parameters in the full model
- About 3 billion active parameters per token
- About 20 tokens per second on a laptop
- About 17 tokens per second on CPU-only hardware
These numbers do not prove that a laptop can replace heavily utilized production infrastructure. They show that the business discussion can begin somewhere else: What process are we improving? What service level does it require? Which data must remain inside the organization? How many users will be active at the same time?
The real change is not that a large model fits on a laptop. It is that an enterprise can match hardware to the process instead of matching the process to the most expensive hardware.
How a large model behaves like a smaller one
In a dense model, each layer activates a large share of the parameters during every stage of response generation. This requires moving substantial amounts of data from memory to the compute units. During LLM inference, memory bandwidth can become as important a constraint as raw processing power.
A Mixture of Experts model works differently. It contains many groups of experts, but a routing mechanism selects only some of them at each stage. If roughly 3 billion out of 34.7 billion parameters are activated for each token, both computation and data movement can decline significantly.
That distinction should not be oversimplified. Inactive parameters are not necessarily parameters that no longer need to be stored or loaded. The complete weights still require capacity in memory, storage, or some combination of the two. Context length, the KV cache, quantization, the operating system, and data-transfer speed also affect real-world performance.
There is no engineering magic here. There is a carefully designed set of trade-offs.
The results are impressive, but not fully comparable
According to the published results, the same weights file ran on hardware ranging from a B200 to a CPU-only server. The performance gaps are enormous, but the type of measurement matters. Aggregate throughput under load is not the same as single-user generation speed, and different hardware may be tested with different memory configurations, levels of parallelism, and context lengths.
Reported inference throughput by hardware:
- Single B200: 18,057 tokens per second
- A10G: 126 tokens per second
- Laptop with 8 GB of VRAM: 20 tokens per second
- CPU-only server: 17 tokens per second
These results illustrate why premium GPUs are not about to disappear from large AI workloads. A B200 serves a completely different category of volume and concurrency. At the same time, 17 to 20 tokens per second may be perfectly useful for local workflows that do not require hundreds of simultaneous users or rigid response-time guarantees.
- Advanced GPU: Its main advantage is throughput and concurrency. Its main constraints are cost and procurement, making it appropriate for large-scale services.
- Modest GPU: It offers a balance between performance and cost, but has limited capacity. It may suit a team or department.
- Laptop: It provides mobility and privacy, but supports little concurrent load. It is best suited to individual and field work.
- CPU-only hardware: It can reuse existing infrastructure, but usually introduces higher latency. It may be suitable for background and batch tasks.
Tokens per second are therefore not a business KPI on their own. An enterprise should measure time to complete the process, exception rates, cost per task, output quality, and the amount of human intervention required.
What this means for enterprises: more deployment options
Many enterprises operate under privacy, regulatory, commercial confidentiality, or connectivity constraints. Banks, hospitals, defense organizations, government agencies, manufacturers, and companies with field operations cannot always send sensitive information to an external AI service.
Efficient local inference can open several practical deployment scenarios:
- Processing sensitive documents without sending their contents to a public cloud.
- Supporting field workers when connectivity is limited.
- Running retrieval-augmented generation over an internal repository in an isolated environment.
- Performing document classification, extraction, and quality control on existing servers.
- Adding a local AI layer to legacy operational systems.
- Maintaining a basic level of service during an external provider outage.
The value is not limited to reducing cloud costs. Local deployment can improve control, resilience, and response time. It also transfers responsibility to the enterprise, including model updates, security, permissions, monitoring, quality assurance, and version management.
Watch out: A laptop is not an AI strategy. A successful local demonstration does not prove production readiness. Quality, load, security, licensing, maintenance, and long-term total cost must all be tested.
The risk of buying hardware before understanding the process
Enterprises often begin by asking which GPU they should buy. That is usually the wrong first question. The decision should begin with a map of the business process: Who makes the decision? What data is available? What is the cost of an error? How often does the process occur? What would count as a meaningful improvement?
AI is not solely a technical project. It is a multidisciplinary field that combines computer science, process understanding, risk management, organizational economics, and user experience. Relevant education and practical experience are not decorative credentials. They are prerequisites for choosing the right model, infrastructure, and controls.
This is especially important for small and midsize businesses, which may receive confident recommendations from self-appointed experts. Installing a local model can look simple in a demonstration video, but building a stable solution requires knowledge of memory, quantization, security, response quality, operations, and business context. A poor choice can create higher hidden costs than a managed cloud service.
Keep a human in the loop, but not in every action
Efficient local models allow enterprises to run AI agents close to their systems and data. This creates meaningful potential for operational efficiency. AI can perform nondeterministic tasks that previously required human judgment, such as reviewing a document, identifying an anomaly, drafting a recommendation, or routing a case.
A human in the loop remains critical only when that role is designed correctly. If an employee must approve every model action, the organization has not created automation. It has created another approval queue. The goal is for an employee who previously supervised one process to oversee dozens or hundreds of process instances while concentrating on exceptions and high-risk cases.
That requires:
- Confidence thresholds that distinguish automatic action from escalation.
- Clear policies governing which actions an agent may take.
- Complete records of inputs, decisions, tools, and outcomes.
- Exception monitoring instead of manual review of every answer.
- The ability to stop, restore, and quickly transfer work to a person.
A method for evaluating local inference
Instead of declaring a broad move to either the cloud or on-premises infrastructure, run a focused experiment on one process. The experiment should compare configurations, not only models: a cloud service, a local GPU, existing hardware, and a hybrid approach.
- Define the process: Select a task with clear volume, cost, risk, and success metrics.
- Create a baseline: Measure time, quality, exceptions, and cost in the existing process before introducing AI.
- Test several configurations: Compare cloud services, a local GPU, CPU-only hardware, and a hybrid alternative using the same test cases.
- Apply a realistic load: Test concurrency, long contexts, failures, and dependencies on enterprise systems.
- Design supervision: Define automation thresholds, escalation paths, recordkeeping, and human accountability.
- Calculate total cost: Include hardware, electricity, maintenance, security, staffing, and upgrades.
The evaluation should use appropriately handled real-world data and a task set that represents the actual work. A general question-and-answer benchmark is not enough to select infrastructure for a financial, medical, legal, or industrial process.
Two tracks must advance together
Lower local inference costs do not solve the adoption challenge. Enterprises need to progress along two tracks at the same time.
The first is AI literacy. Employees and managers need to learn how to communicate with models, recognize weak answers, protect information, and understand when verification is required. Personal AI tools can create substantial value, but they also require changes in working habits.
The second is agent development. AI should be integrated into an existing process so employees do not need to open a separate tool and initiate every action themselves. A well-designed agent can operate within email, a customer service platform, an ERP system, or a document workflow. It may be more technically complex, but it can sometimes be easier to adopt because it does not radically change the employee experience.
For this approach to scale, companies need internal capabilities for building and managing AI agents. Information systems departments will gradually be expected to manage a digital workforce as well as software: permissions, roles, performance, exceptions, versions, and termination. In that sense, they will become the human resources department for agents.
Is the era of expensive GPUs beginning to crack?
Yes, but not because powerful accelerators have become unnecessary. The crack appears somewhere else: in the automatic connection between a meaningful AI model and expensive infrastructure.
Advanced GPUs will remain essential for training, high throughput, concurrency, and demanding models. At the same time, sparse models, quantization, and efficient inference engines will expand the range of workloads for which laptops, workstations, and CPU servers can deliver real value.
The management implication is a shift from uniform procurement to tiered architecture. Heavy workloads can run in the cloud or on centralized GPUs. Sensitive information can remain in a local environment. Simpler tasks can run at the edge. Not every request needs the same model, hardware, or service level.
The enterprises that gain an advantage will not necessarily be those that buy the most powerful accelerator. They will be the ones that connect deep domain knowledge, AI engineering, business processes, human oversight, and infrastructure economics. Hardware is becoming more accessible. The responsibility to design the system well is only increasing.